How Travel Ruter combined typed decisions, scoped evidence and additive tool loading to reduce response time and inference cost in a controlled comparison with its legacy architecture.
Abstract
Travel Ruter’s assistant operates on a persistent itinerary, where an answer may require reading a saved note, identifying a specific visit, proposing a change and verifying what was stored. We integrated TypeSafe’s JEV into this workflow to select useful evidence and capabilities before the main language model spends additional calls discovering them. A new Portuguese trip provided ten previously unexecuted, four-turn scenarios, run against an archived legacy architecture and the current JEV-enabled implementation using the same GPT-6 Luna model. Across 40 turns per arm, mean completion latency fell from 12.16 to 6.70 seconds and usage-derived inference cost, including JEV, fell by 41.7%. Response acceptance under the frozen rubric rose from 25/40 to 32/40; correct persisted outcomes remained 5/6 in both systems. These findings support retaining the integrated design for this workload. They do not isolate JEV’s contribution from its surrounding engineering or establish general superiority: the evaluation is small, nonblind and sensitive to instruction-compliance criteria. The evidence nevertheless explains a practical improvement: substantially less work reached Luna, while conversation prefixes remained stable and measured cache reuse increased. [E1]
1. A travel plan is a changing application state
Travel Ruter brings destinations, saved research and scheduled visits into one application. Its assistant helps users work with that material through conversation: compare activities against a budget, turn a recommendation into a point of interest, adjust a visit’s duration, or reorganize a day while preserving an existing reservation. This makes the assistant’s problem more demanding than producing an appealing itinerary. It must distinguish the current plan from supporting research, interpret the user’s latest constraint, select the correct persistent record and explain whether a proposed change has actually been saved. A plausible paragraph about Lisbon can still be a failed response if the user asked about a similarly named place in Porto, if a relevant note was ignored, or if the assistant reports a write that never occurred.
A note is a persisted document associated with a trip. Its title, content and type give it a documentary identity, while links to a destination, day or point of interest establish where its information applies. A note might record a group price, a temporary closure, a personal preference or a reservation condition. A point of interest (POI) represents a structured visit, with fields such as identity, destination, duration, cost, currency and scheduling information. These objects serve different roles in a task: the note supplies evidence for a decision; the POI is often the record the application must change. Their relationship is therefore part of the evidence. A 75-minute recommendation attached to one café cannot safely update another café merely because the names match. Figure 1 places these objects within the agent’s execution path.
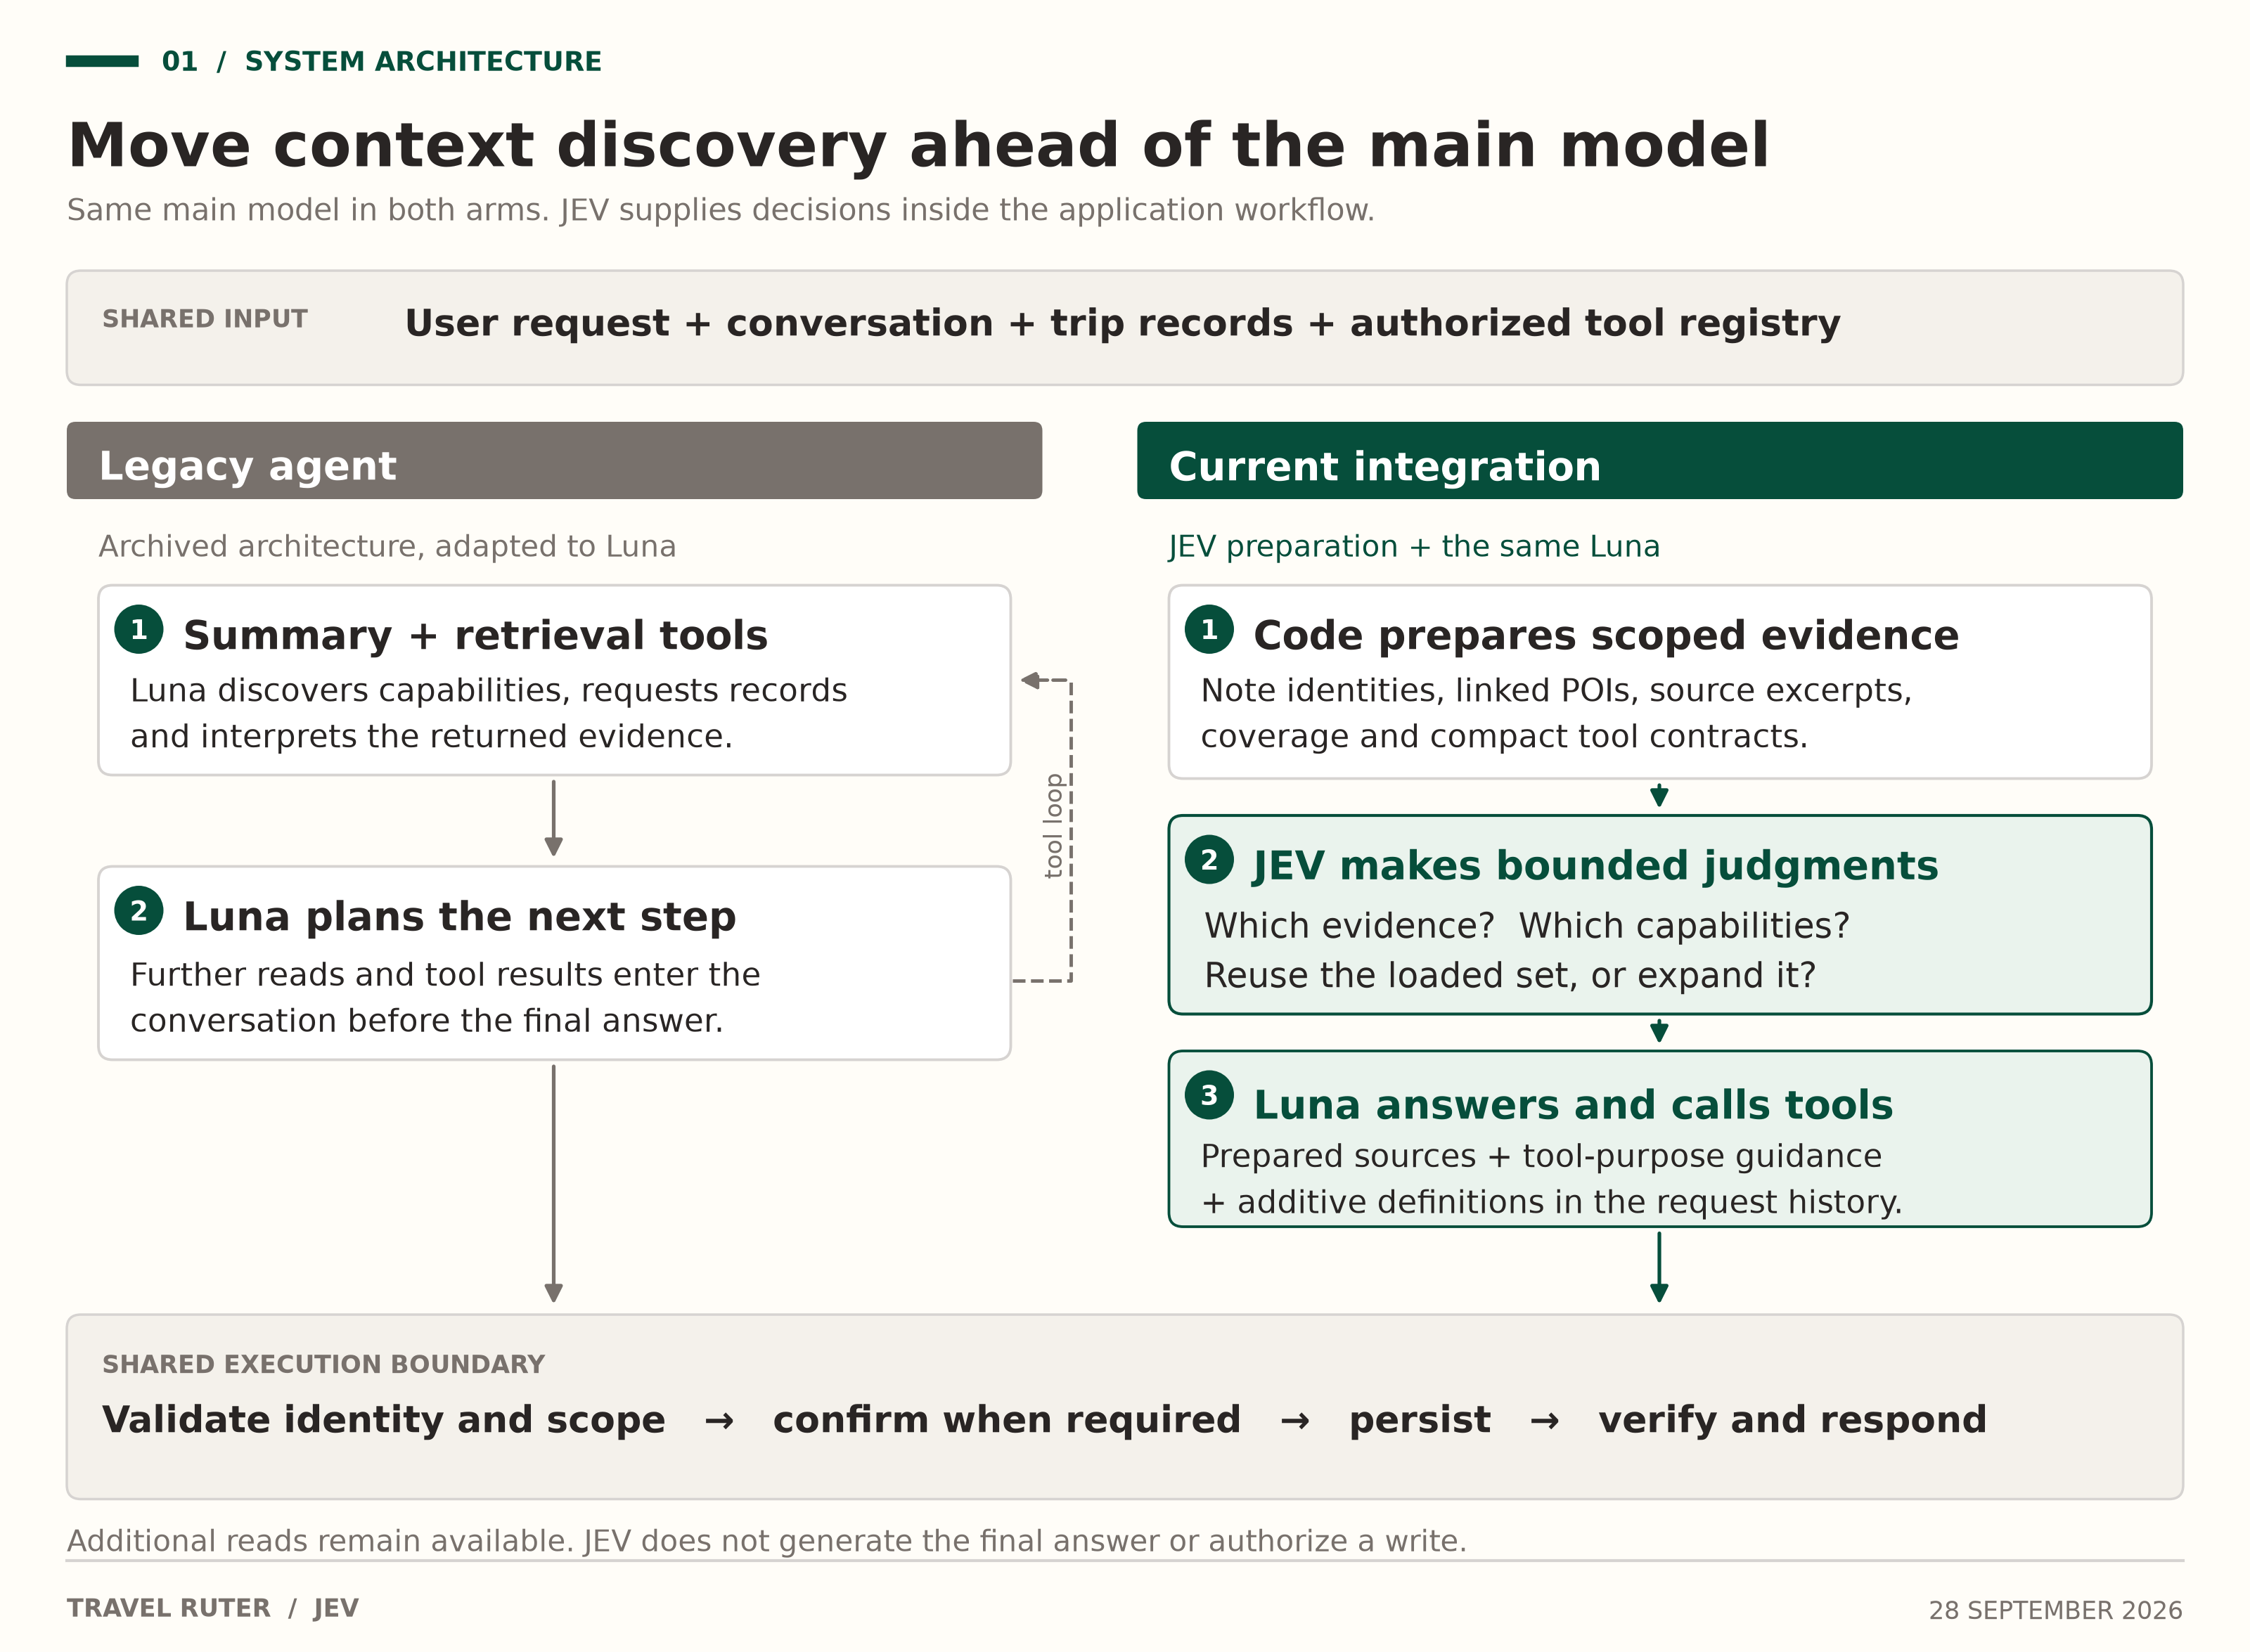
Figure 1. Legacy and JEV-enabled workflows, both using the same Luna model. The preparation stage moves bounded evidence and capability decisions ahead of Luna; the shared execution boundary retains validation, confirmation and persistence. Both paths can request additional reads. This is a conceptual architecture comparison, not a measured sequence of calls. The separate memory-update agent is outside the experiment.
The legacy agent, our previous architecture without JEV, already used application tools to expose trip state to a Pydantic AI agent. It did not indiscriminately paste every note into every initial prompt: it supplied a trip summary and let the model discover capabilities and request further material through programmatic retrieval. The optimization target was the work between those steps. Broad capability discovery, repeated reads and loosely scoped evidence can make the main model spend several requests assembling information the application could have prepared more directly. Both architectures were evaluated with the same Luna model. Consequently, this study compares a legacy reference with the current integrated system, rather than comparing two revisions of JEV or calling the current implementation with JEV disabled.
2. Where JEV belongs in the workflow
TypeSafe describes JEV as a System One model that returns typed decisions and probabilities from application state, rather than generating the user’s answer. That distinction shaped the integration. We use it to judge whether a known tool is relevant, what purpose that tool serves, and which candidate evidence supports the current request. Application code still retrieves records, validates identifiers, constructs context and enforces permissions. Luna remains responsible for interpreting the selected evidence, deciding the next permitted action and explaining the result. JEV is therefore a decision component inside the existing agent workflow, not an additional autonomous agent with an independent conversation or authority to modify the trip. Its typed interface makes outputs easier to consume; it does not guarantee that a selected tool or document is correct. [1]
Three integration points emerged during development. Tool selection was a natural early fit because the answer space was already bounded by a server-owned registry. Note selection required more work on representation: relevance depended on document identity, scope and relationships, not simply whether a passage mentioned the destination. We also explored filtering web evidence, but the earlier experiment did not demonstrate a useful reduction in downstream web calls, so that step was discarded. This history explains the retained design without treating exploratory measurements as part of the present benchmark. In particular, web research remains an available application capability, but JEV web-evidence filtering is inactive and the Portuguese scenarios do not measure live search quality. [E2]
Table 1. The three integration points and their role in the current system.
| Integration | Intended benefit | Decision |
|---|---|---|
| Tool selection | Expose capabilities relevant to the task, with guidance about their purpose | Retained, with reuse and additive loading |
| Note evidence selection | Deliver useful, scoped source material before unnecessary model-led retrieval | Retained, with structured metadata, coverage and deterministic shortcuts |
| Web-evidence filtering | Reduce downstream work by selecting among external evidence | Discarded after exploratory evaluation; inactive in this study |
3. Preparing evidence the model can actually use
The note integration improved when we treated each candidate as evidence with a provenance, rather than as an anonymous piece of text. The representation includes its identifier, title, type, linked entities, an excerpt and whether that excerpt is truncated. JEV receives the user’s request alongside this structured state. Application code then delivers the selected source span with its metadata, avoiding a mismatch in which the selector judges one passage but Luna receives a different window. Multi-part requests also receive coverage judgments so that a strong match for one topic does not crowd out the only evidence for another. These are implementation choices in Travel Ruter; TypeSafe’s state guidance supplies the broader principle of including the identities and relationships needed to answer a typed question. [2]
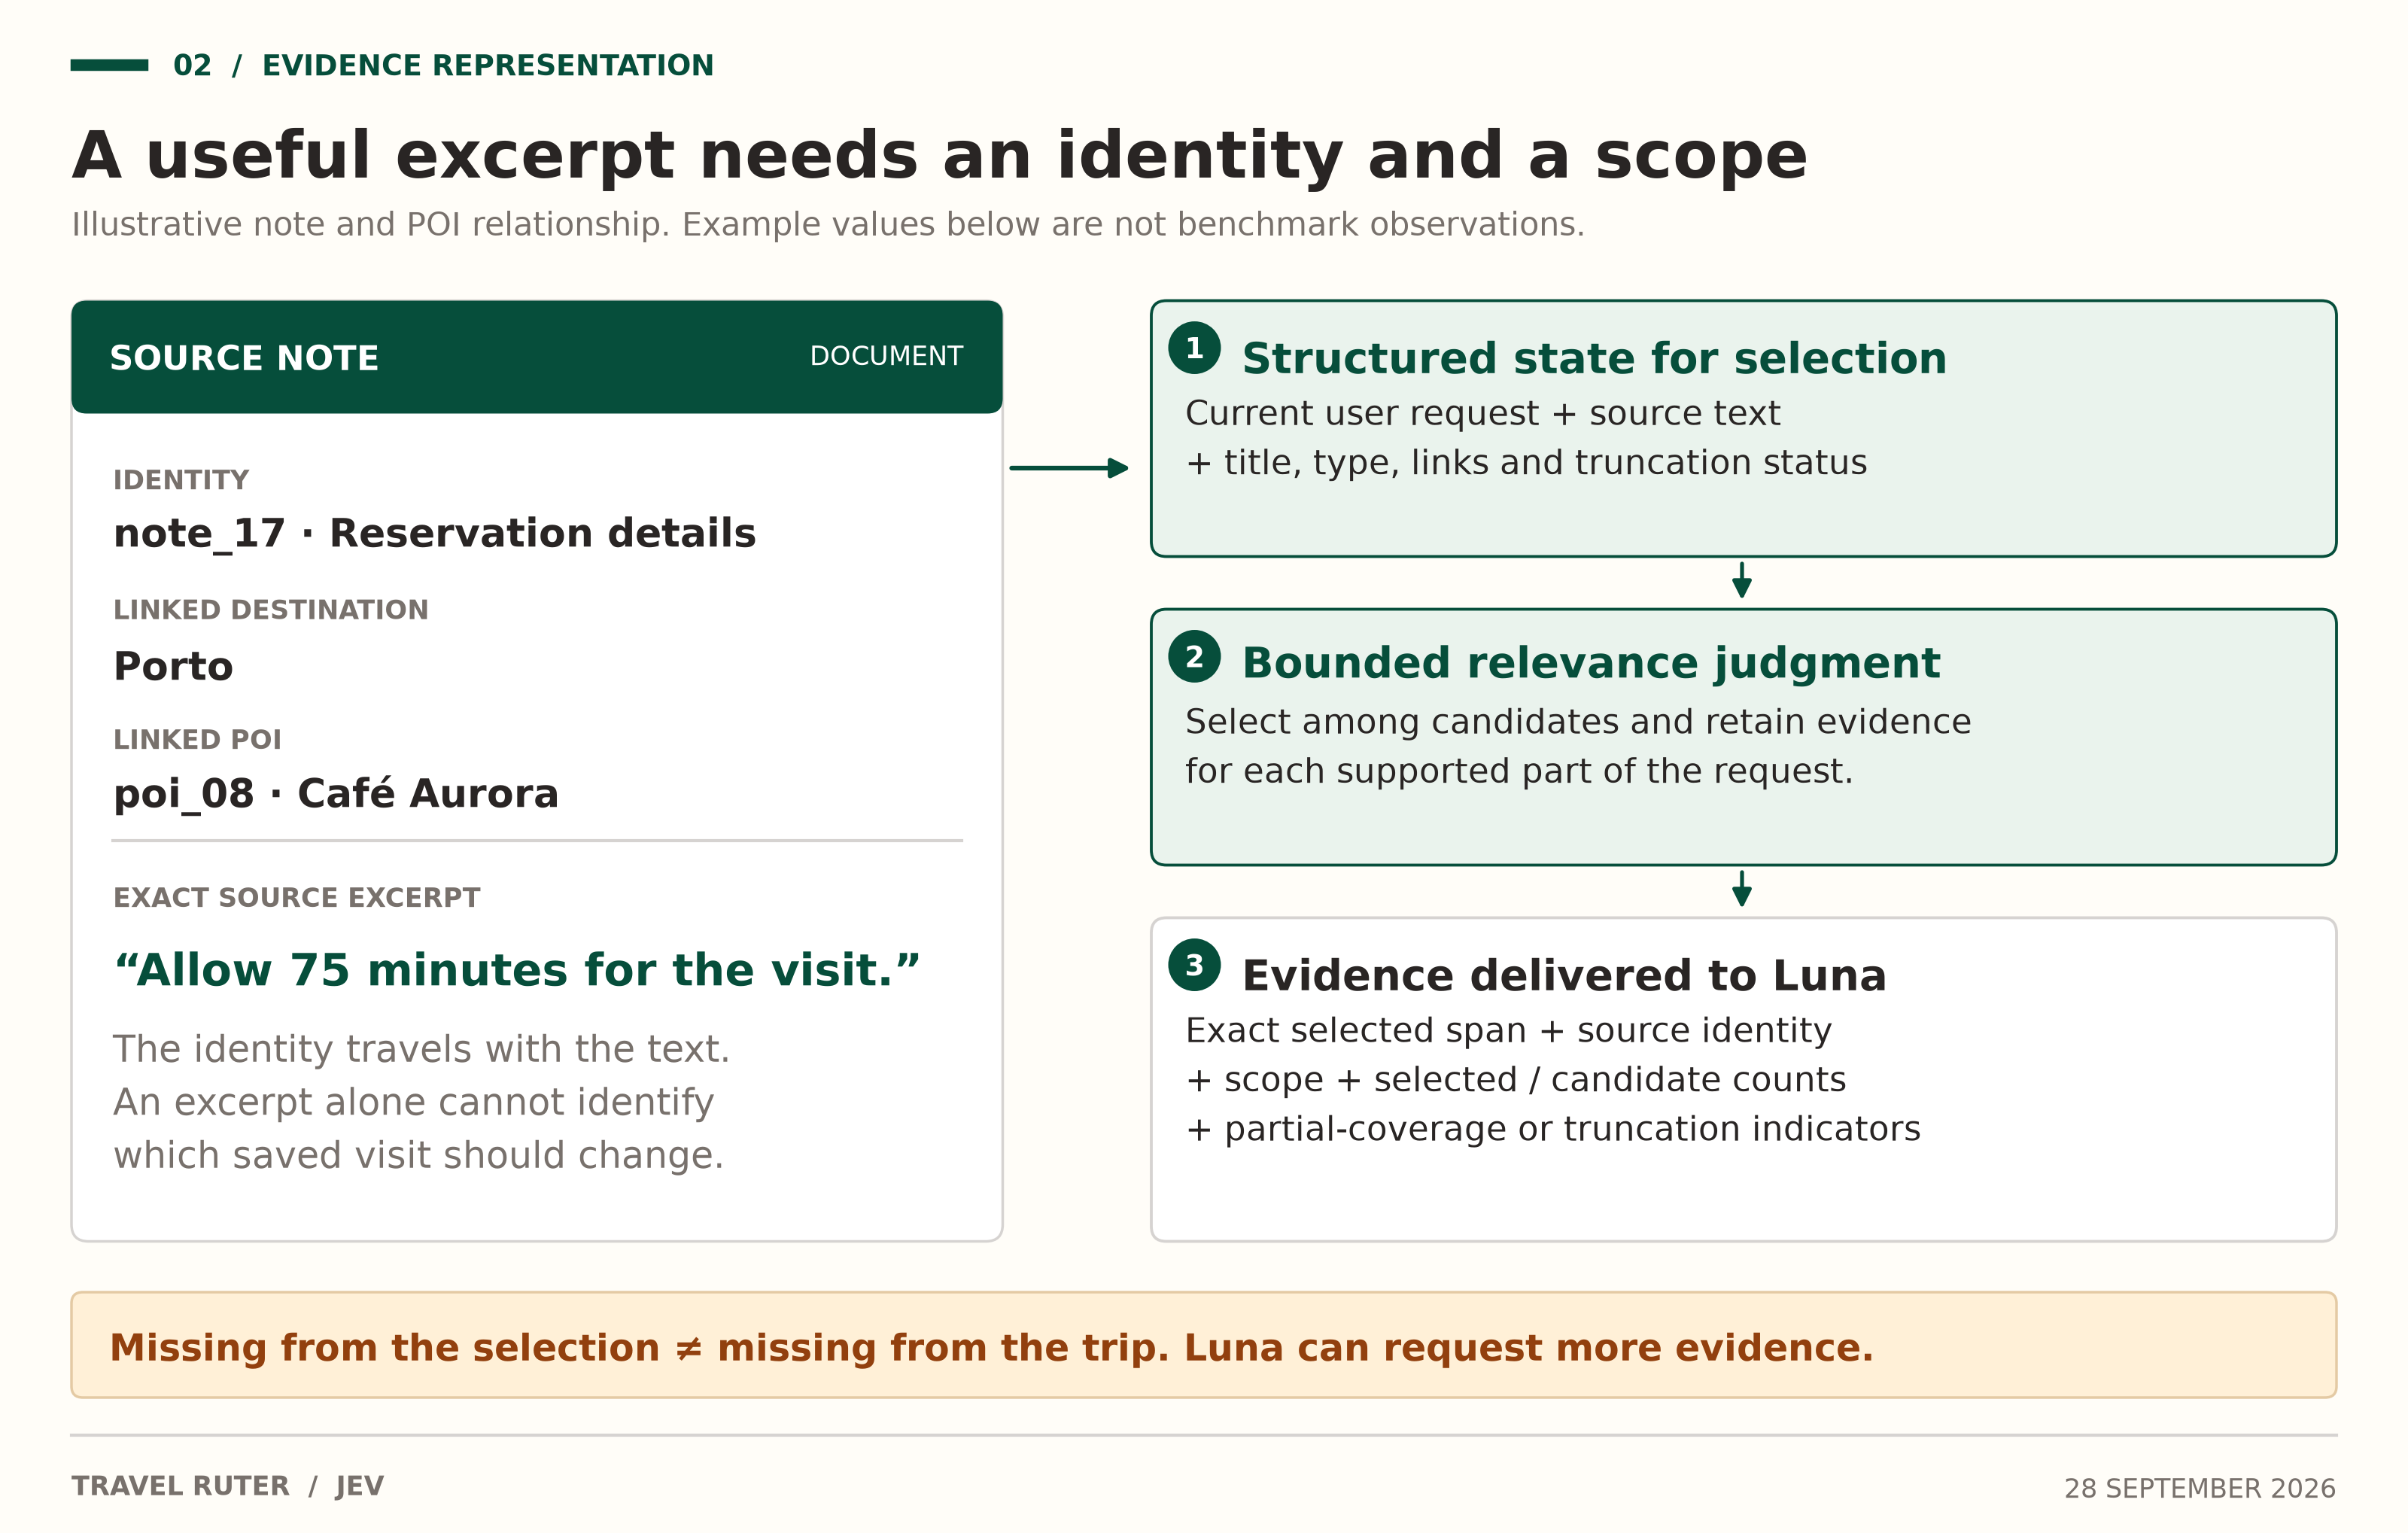
Figure 2. Anatomy of the semantic evidence path. The note, identifier and quoted text are illustrative, not a captured benchmark response. Source relationships prevent a relevant excerpt from being applied to the wrong POI; coverage metadata tells Luna what the selection does not establish. Small, complete scoped collections can bypass the semantic judgment, as described below.
Selection is not mandatory for every corpus. When a scoped collection is already small enough to fit completely within the bounded preparation payload, code passes the complete collection and avoids an unnecessary JEV ranking request. Larger collections use semantic selection with deterministic fallback evidence if the judgment is unavailable. Every payload also describes its coverage: how many notes were in scope, how many became candidates, which excerpts were delivered and whether material was omitted. This matters because “the selected notes do not mention a train time” is different from “the trip contains no train time.” The main model can request more evidence when the task changes or the current selection cannot answer it. A preparation layer that saves tokens by concealing its omissions would make the assistant cheaper by weakening its reasoning conditions; this implementation instead exposes the limits of the selection.
Repeated preparation can itself become waste. Previously selected evidence can be reused when it remains current and relevant to the task. Freshness and relevance remain separate: unchanged source documents do not prove that an earlier selection covers a new question. Coverage guidance preserves that distinction, and current POI state is read afresh where needed. The result is a selective workflow with an escape route, rather than a one-time summary that permanently replaces the trip’s documents. This mechanism also explains why a useful JEV integration can include fewer JEV calls: deterministic sufficiency checks and valid reuse are part of the optimization.
4. Selecting tools without rewriting the cached conversation
Tool selection uses compact contracts describing what each capability does, its prerequisites and the distinction between reading, changing, verifying and researching. JEV makes a bounded purpose decision for each candidate; code translates that decision into instructions for Luna. These instructions are application-authored guidance, not an explanation generated by JEV. Tools are excluded only when the negative judgment is sufficiently confident, so uncertainty does not silently remove a needed capability. On a follow-up, the router first considers whether already loaded capabilities can satisfy the new request. It still checks the current task; it does not reuse an old permission or assume that previously observed evidence authorizes a new write. TypeSafe’s function-calling cookbook illustrates the related pattern of mapping language onto a closed set of functions, although Travel Ruter retains Luna as the tool-calling model. [3]
The cache strategy concerns how those definitions reach the provider. Replacing the whole tool catalogue on every task change can alter request material that earlier calls reused. The evaluated workflow adds newly needed capabilities while preserving the earlier conversation. If the first task loads three capabilities and the next needs four additional ones, the earlier definitions remain in place and the new definitions are appended. Permission and capability changes take precedence over cache reuse.
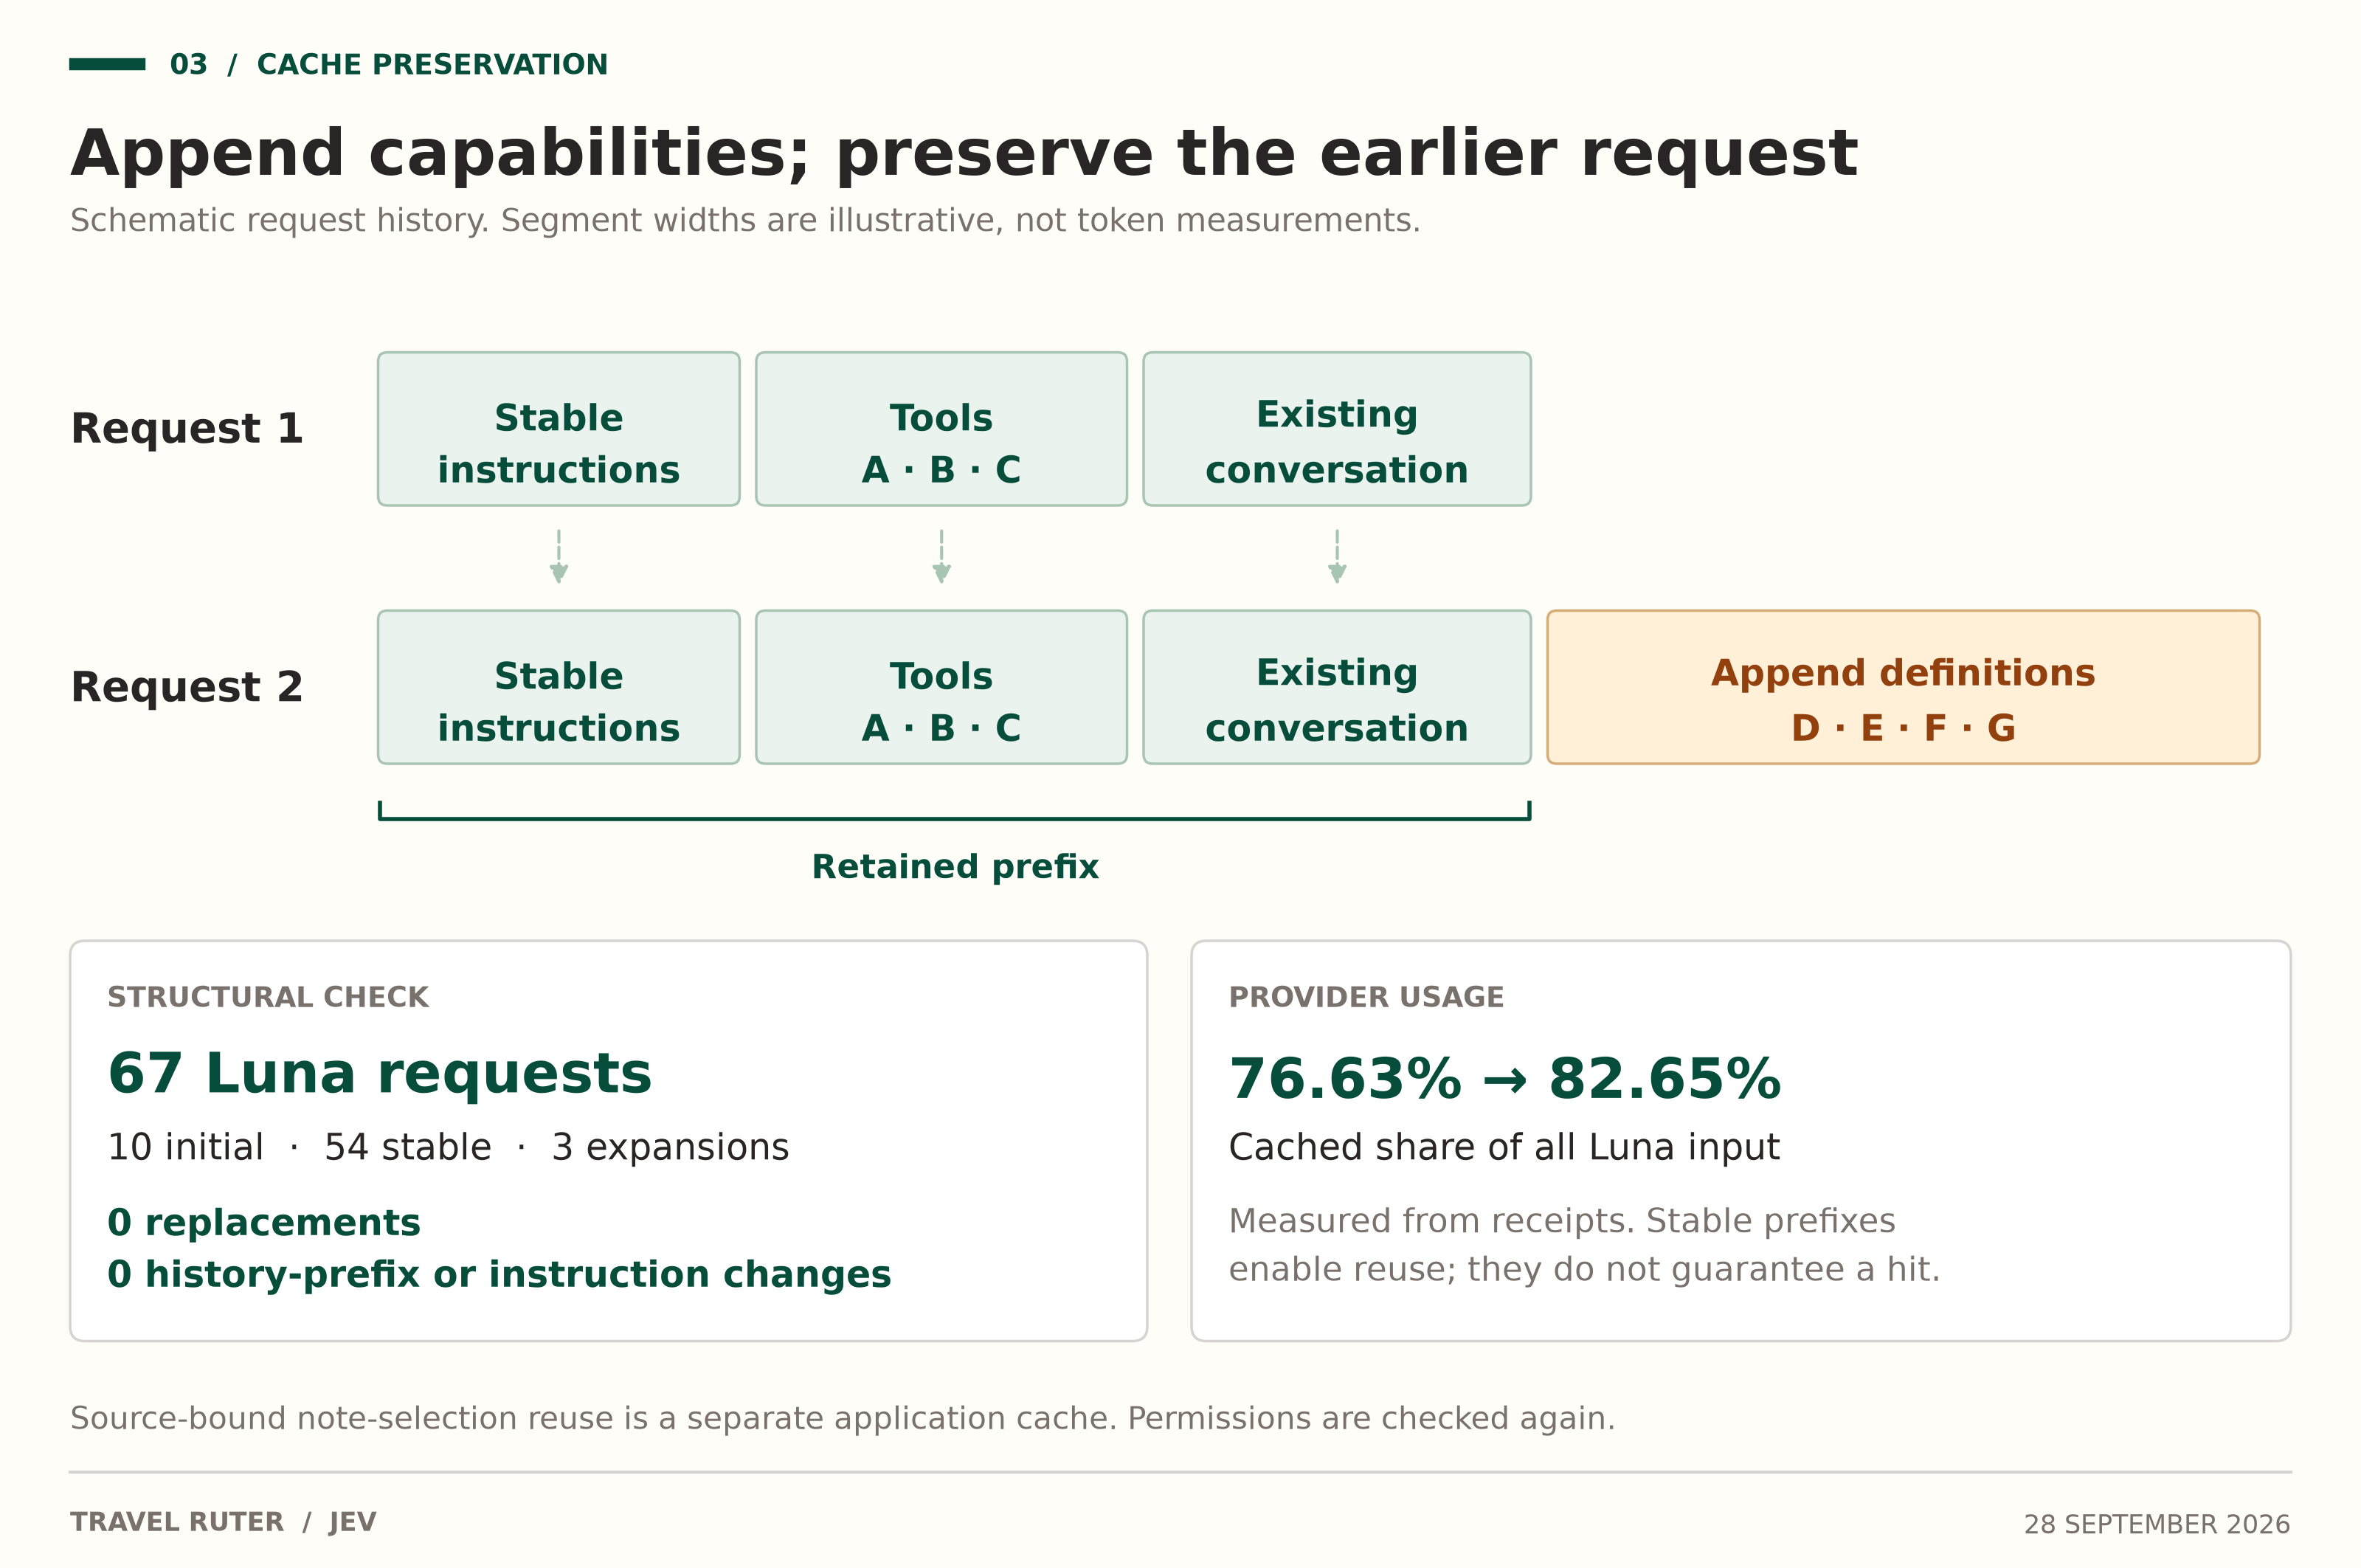
Figure 3. Illustrative three-tool then four-tool expansion, alongside measured request transitions. In the JEV arm, 67 Luna requests comprised ten initial catalogues, 54 stable transitions and three additive expansions. No catalogue replacement, input-history prefix change or instruction change was observed. This is structural evidence; the provider’s cached-token receipts separately establish actual reuse.
Application-level selection reuse and provider prompt caching are different mechanisms. The former avoids repeating preparation; the latter reduces repeated processing of reusable input. OpenAI’s documentation describes caching in terms of eligible matching prefixes and boundaries, so preserving history is an enabling condition rather than a guarantee of a hit. We therefore inspected both serialized requests and provider usage. In this run, the cached share of Luna input increased from 76.63% to 82.65%, while total Luna input fell substantially. All first requests reported zero cached input in both arms, but we did not claim to flush the provider’s cache. The measured result is narrower and more useful: this implementation reduced model work without sacrificing the observed continuity of its request prefixes. [4, E1]
5. Evaluation: a new trip and ten paired conversations
The final generalization check used a new seven-day trip covering Lisbon and Porto, containing two destinations, eight POIs and fourteen notes. Its prices, opening constraints and reservation details were controlled fixture facts, not verified travel advice. Ten scenarios exercised budget reasoning, homonyms, date-specific corrections, multilingual notes, aliases, replanning, preference exceptions, missing information, malicious text inside a document and changes of task within a conversation. Each scenario contained four user turns and ran once per architecture against an isolated copy of the same initial state. Scenario order was shuffled with a fixed seed and the first arm alternated across pairs. The prompts and expected outcomes were frozen before execution; we made no implementation changes or outcome-driven reruns during this holdout. [E1]
Both arms used the provider-reported gpt-6-luna; JEV calls reported jev-1.13.0. The comparison used the legacy architecture and the current JEV-enabled system. Their infrastructure was development infrastructure, not live user traffic. The harness applied the same operation-specific approval policy, exercised real persistence and checked final state independently of the assistant’s claims. External discovery tools returned controlled unavailability rather than executing live searches, allowing us to inspect whether the agent respected requests to work from supplied notes. This is a controlled task evaluation of an application workflow, with realistic dependencies and writes, rather than a general benchmark of travel knowledge or browsing. [E1]
We defined response acceptance as a binary judgment that the delivered answer satisfied its turn’s factual, instruction and action requirements. Strict conversation success required every turn to pass and the final state to match; mutation success considered the expected saved state in the six conversations involving changes. These denominators answer different questions and should not be collapsed into an unexplained quality score. Grading was performed by the Codex session that implemented the harness, with access to arm identity and traces. It was not a blinded or independent Astra 6 evaluation. Latency ran from the REST request to terminal completion, including permitted approval continuations and instrumentation, but excluding fixture creation and later review. It is completion latency, not time to first token. [E1]
Inference cost was reconstructed from provider usage and the benchmark’s fixed tariffs, including JEV and cache-write charges. It excludes infrastructure, Logfire storage and review effort, and is not a reconciled provider invoice. All 242 provider receipts had complete usage and matched the corresponding Logfire cost records. The existing development Logfire export also reconciled all 970 local spans: 930 tagged benchmark spans and forty startup test-model spans, which were not paid generations. Logfire made the execution auditable by connecting model requests, tool activity, token usage and duration; it did not supply the quality verdict. The publication uses those completed exports rather than collecting a new run. [5, E1]
6. Results: less Luna work, lower latency and lower total cost
Table 2. Latest Portuguese holdout, ten conversations and forty user turns per arm. Cost is usage-derived USD for the complete arm; cached share is cached Luna input divided by all Luna input. The acceptance rubric and its sensitivities are discussed below.
| Metric | Legacy agent + Luna | Current integration + same Luna |
|---|---|---|
| Accepted responses | 25/40 (62.5%) | 32/40 (80.0%) |
| Strict conversation success | 0/10 | 6/10 |
| Correct mutation outcomes | 5/6 | 5/6 |
| Mean completion latency | 12.16 s | 6.70 s |
| Median completion latency | 9.28 s | 6.39 s |
| p95 completion latency | 25.52 s | 11.99 s |
| Total inference cost | $0.058526 | $0.034092 |
| Luna cost | $0.058526 | $0.026070 |
| JEV cost | $0 | $0.008022 |
| Luna requests | 120 | 67 |
| JEV requests | 0 | 55 |
| Total provider requests | 120 | 122 |
| Luna input tokens | 1,214,560 | 689,907 |
| Luna output tokens | 27,499 | 10,817 |
| Cached Luna input tokens | 930,737 | 570,190 |
| Luna cache-write tokens | 283,463 | 119,516 |
| Cached share of Luna input | 76.63% | 82.65% |
The principal efficiency result is a 44.9% reduction in mean completion latency and a 41.7% reduction in total inference cost. The cost accounting matters: Luna alone became cheaper by more than the final saving, but JEV added $0.008022 of inference. After including that overhead, the candidate still cost $0.034092 against $0.058526 for the reference. Total provider requests did not decrease: 67 Luna calls plus 55 JEV calls slightly exceeded the reference’s 120 Luna calls. What changed was the allocation of work. Luna processed 43.2% fewer input tokens, generated 60.7% fewer output tokens and made 44.2% fewer requests. Those observations are consistent with replacing expensive discovery and repetition with smaller decisions and prepared evidence; they do not establish the isolated causal effect of each component. [E1]
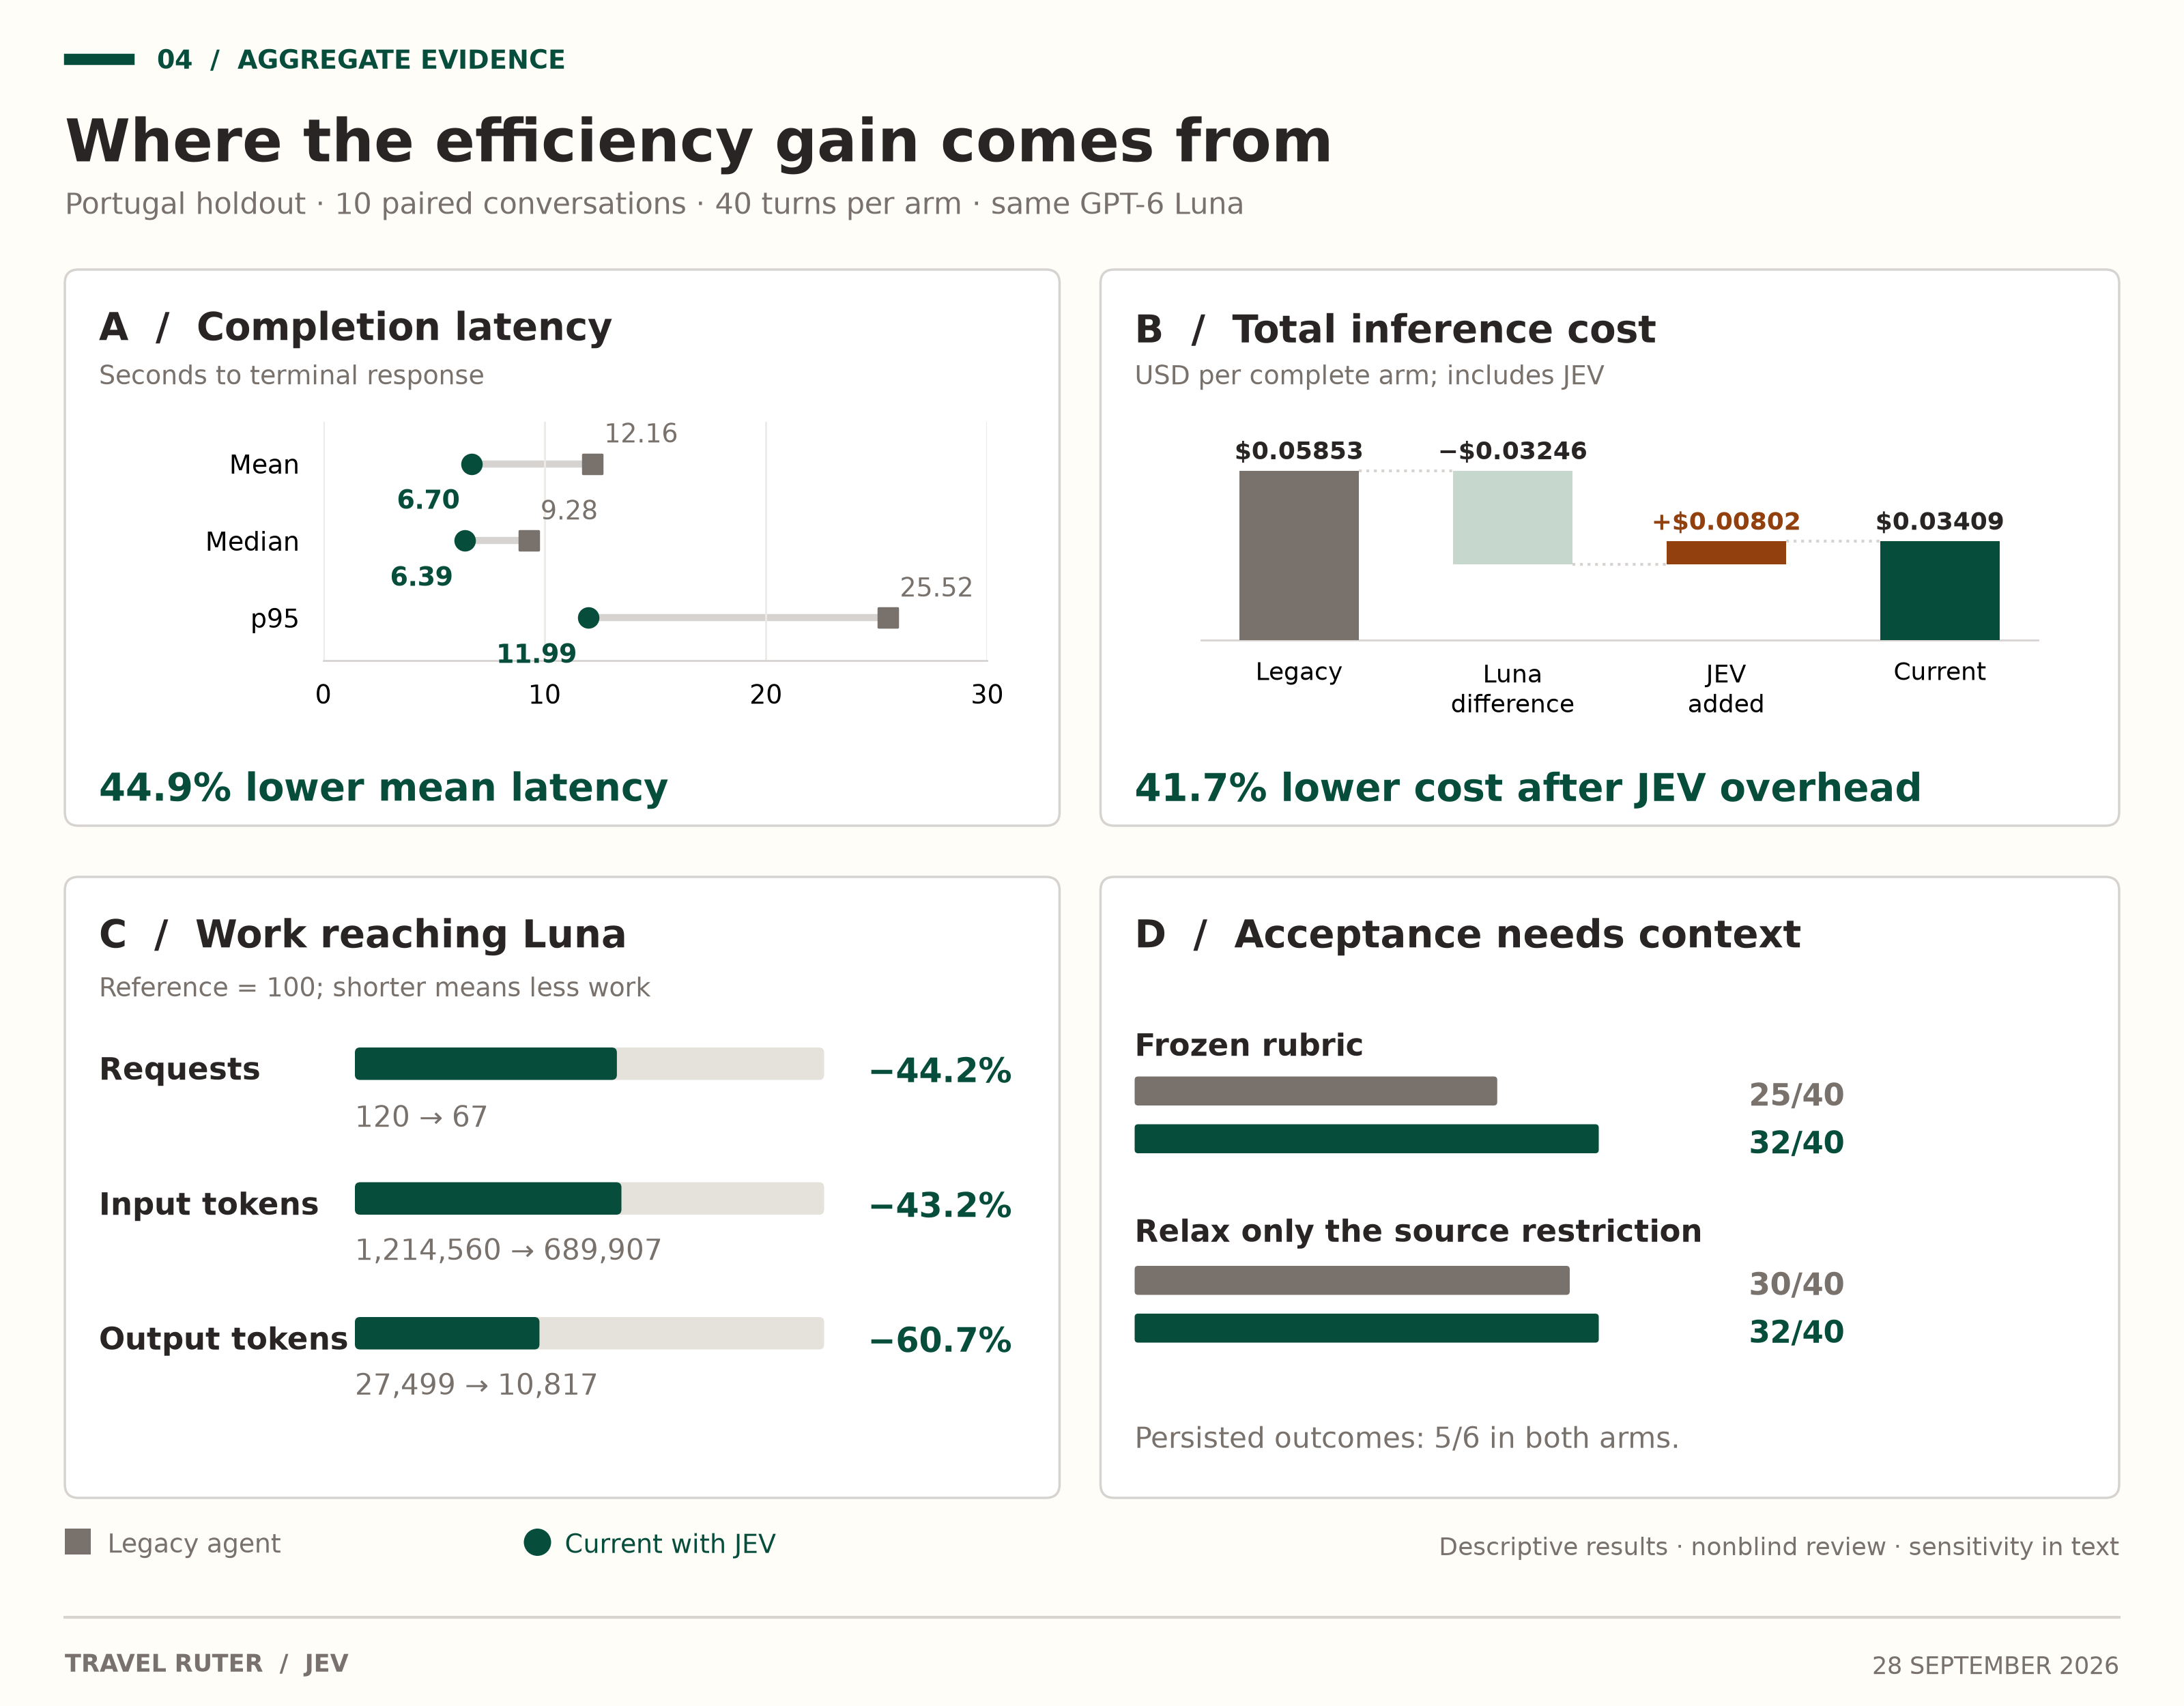
Figure 4. Four views of the same paired holdout. A: mean, median and p95 completion latency. B: accounting waterfall from reference cost, subtracting the Luna cost difference and adding JEV inference; cache-write charges are included. C: Luna requests and token volumes relative to the reference. D: response acceptance under the frozen rubric and after relaxing only the source restriction. The cost decomposition is accounting, not a component ablation. Grading was nonblind; the alias-prompt ambiguity is addressed in the text. No population-level superiority is claimed.
The aggregate hides useful differences between tasks. Budget reasoning showed the largest reduction in both latency and cost, while a date-specific schedule correction and a rain replan also became faster and more consistently accepted. The local preference exception saved little money despite a clear latency improvement, illustrating why a faster response does not imply the same proportional cost reduction. Conversely, the missing-train-information case became slower and more expensive without improving acceptance. Nine of ten scenarios had lower mean latency and total cost with JEV; seven had more accepted responses and three tied under the frozen rubric. Table 3 retains every case, including the regression and the ambiguous alias scenario, so the favorable average does not erase the conditions under which the design still struggles. [E1]
Table 3. Paired scenario results. Acceptance is out of four turns. Cost change includes all inference; negative means cheaper with JEV. Values are rounded from the retained receipts.
| Task | Accepted: reference → JEV | Mean latency: reference → JEV | Cost change |
|---|---|---|---|
| Group budget from notes | 3/4 → 4/4 | 25.19 → 6.22 s | −75.7% |
| Cafés with the same name | 3/4 → 3/4 | 15.56 → 9.69 s | −46.7% |
| Date-limited schedule correction | 3/4 → 4/4 | 9.82 → 4.48 s | −40.9% |
| Portuguese menu and note update | 3/4 → 4/4 | 9.57 → 7.21 s | −36.4% |
| Alias and duplicate resolution* | 3/4 → 4/4 | 9.26 → 5.31 s | −31.1% |
| Rain replan preserving an anchor | 3/4 → 4/4 | 15.81 → 8.34 s | −52.7% |
| Local exception to a preference | 3/4 → 4/4 | 10.16 → 6.23 s | −2.8% |
| Missing train conditions | 1/4 → 1/4 | 5.45 → 6.67 s | +16.0% |
| Instructions embedded in a leaflet | 2/4 → 2/4 | 7.41 → 5.39 s | −10.8% |
| Read, edit a note, then edit a POI | 1/4 → 2/4 | 13.38 → 7.45 s | −39.4% |
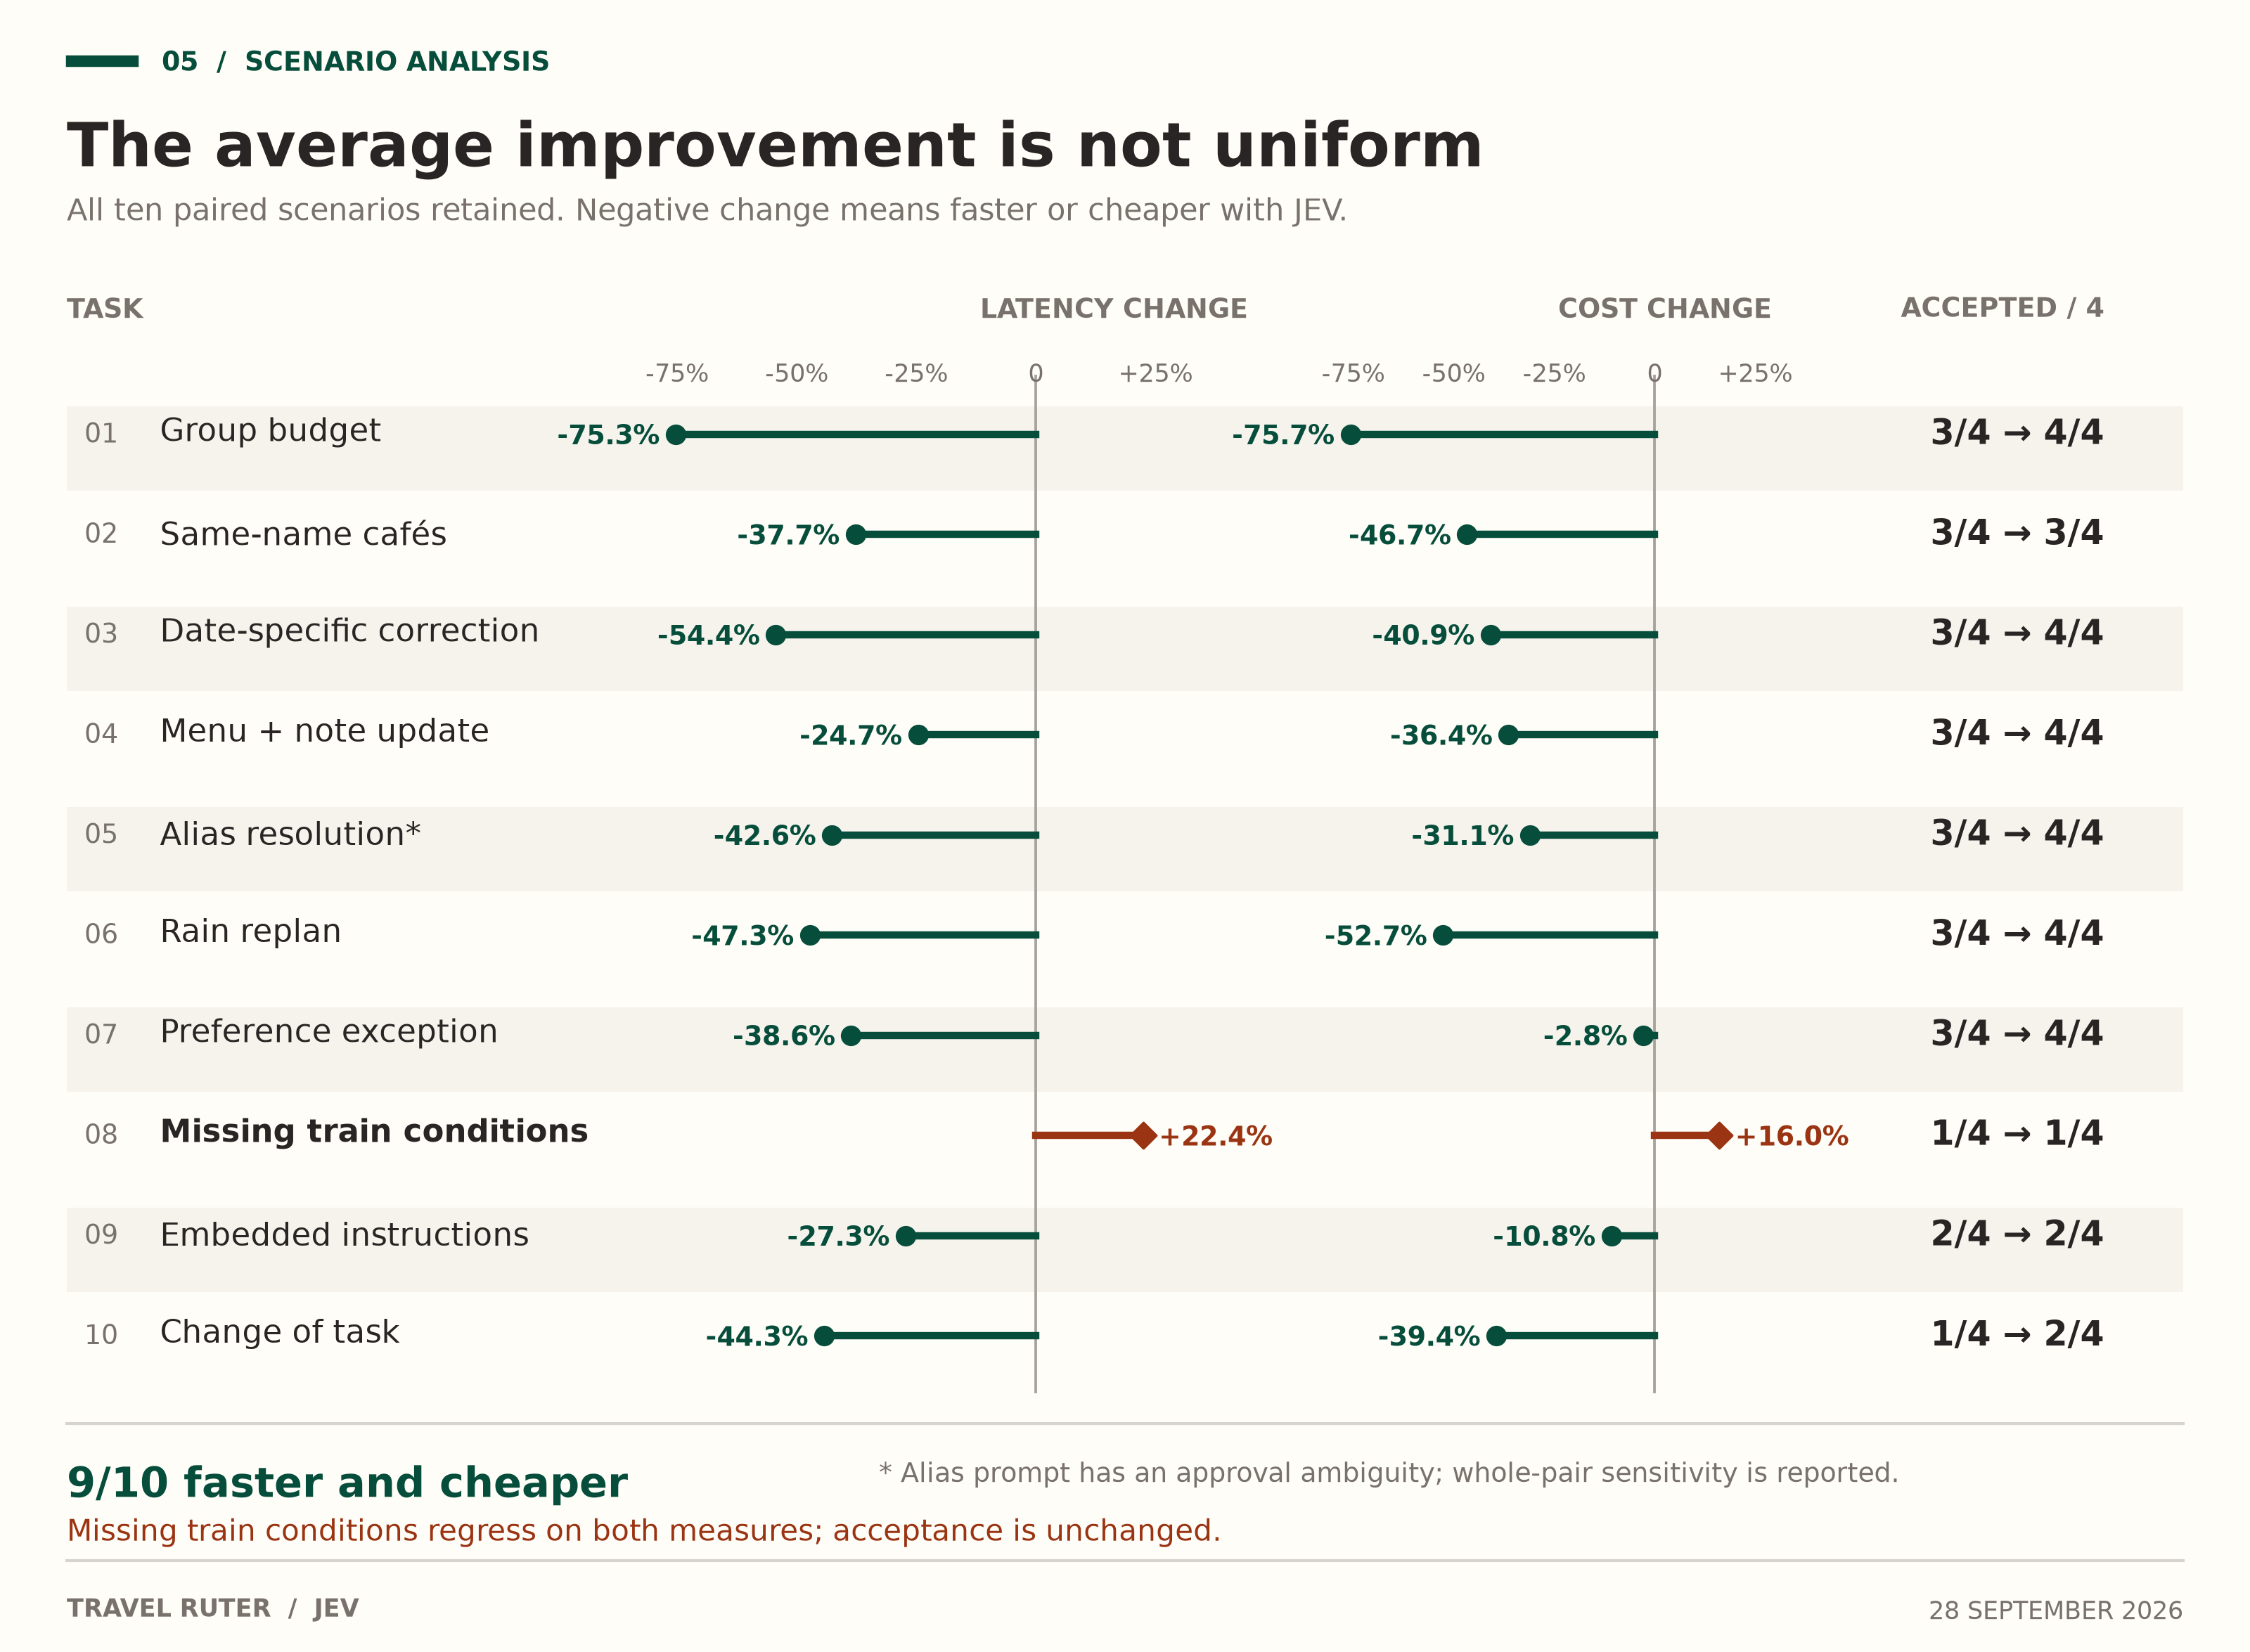
Figure 5. Relative changes for all ten paired scenarios, computed as (JEV / reference − 1) × 100. Each point is a whole-scenario change, not a confidence interval; lines connect that estimate to zero. Latency uses the four-turn mean and cost includes all inference in the scenario. Acceptance counts run from reference to JEV. The missing-train case is the single efficiency regression. The asterisk marks the alias prompt with the disclosed approval ambiguity.
The quality result needs two qualifications. First, the alias prompt could reasonably be read as authorizing an earlier write, while the frozen approval policy expected a proposal at that turn. Excluding that whole paired scenario leaves acceptance at 22/36 versus 28/36, mean latency at 12.48 versus 6.85 seconds, and cost at $0.053244 versus $0.030452. The efficiency direction therefore survives this post-hoc sensitivity check. Second, five reference answers failed because they attempted external discovery despite a notes-only instruction, although their factual content was otherwise acceptable. Relaxing only that restriction changes the full-cohort comparison to 30/40 versus 32/40, or 27/36 versus 28/36 after also excluding the ambiguous pair. Much of the measured acceptance improvement is better task adherence. It would be misleading to present the original 17.5 percentage-point increase as a comparable improvement in factual accuracy. [E1]
7. Why the integration helped, and what it did not fix
The traces support a practical explanation for the improvement. Prepared evidence removed some need for Luna to discover and reread information; task-specific capability guidance reduced unnecessary excursions; reuse avoided repeating preparation that remained valid; and additive loading protected earlier request structure when the task changed. The router reused loaded capabilities in 27 of forty routing events, with no recorded routing fallback. Alongside the lower Luna token and request totals, this makes a coherent account of how the integrated workflow became cheaper and faster. However, the experiment compares complete systems. It does not separately randomize note selection, tool guidance, deterministic shortcuts, transport changes or cache behavior. The defensible attribution is to the JEV-enabled integration as implemented, with these mechanisms supported by execution evidence, rather than to an intrinsic speed or intelligence advantage of JEV alone. [E1]
The remaining failures show why that distinction matters. In the train case, the delivered answer contained a generic unverified-duration message instead of a useful explanation of the missing evidence. In the task-change case, both systems left the target duration unchanged after misinterpreting an instruction to preserve the other café. Neither failure is repaired merely by improving relevance selection. Conversely, the leaflet case exposed a real weakness in the candidate’s evidence path: the main model searched a Lisbon scope, excluding the Porto-linked document before semantic selection, then misattributed a tariff from another note. A ranker cannot recover a document that never becomes a candidate. Because the malicious leaflet was not retrieved, this case also cannot establish resistance to its embedded instructions. [E1]
These observations explain both the favorable acceptance result and its limits. Strict conversation success rose from zero to six, but that stringent metric requires all four turns to pass; it does not mean that the reference was unable to perform application actions. Both architectures produced the correct final state in five of six mutation conversations. The present study contains ten paired conversations, with correlated turns and one execution per arm, so its apparent precision should not be confused with a population estimate. [E1]
8. Conclusion
The current evidence supports keeping JEV in Travel Ruter’s context and tool-selection workflow. On a new controlled trip, the integrated agent answered faster, incurred lower total inference cost and satisfied more of the specified turn-level requirements while preserving the same mutation success count. The engineering contribution is the division of responsibility that made those results possible: application code maintains identity, scope, freshness and permissions; JEV supplies bounded semantic decisions where deterministic matching is insufficient; Luna receives usable evidence and capabilities with less need to assemble them through repeated calls. Stable, additive request construction allows this preparation to coexist with measured prompt-cache reuse. The result is a useful improvement to an existing agent, with explicit failure boundaries, rather than a claim that adding another model automatically makes an agent better. Future evaluation should separate these components experimentally and use independent, blinded grading, but neither is required to recognize the narrower improvement demonstrated by this completed run.
References and evidence
[1] TypeSafe. System One. Model interface, typed decisions and limits of individual confidence. Accessed 28 September 2026.
[2] TypeSafe. State. Structuring the information supplied to a decision model. Accessed 28 September 2026.
[3] TypeSafe. Function calling. Closed-set function and argument selection. Accessed 28 September 2026; cited as a design pattern, not evidence of Travel Ruter performance.
[4] OpenAI. Prompt caching. Prefix reuse and cache boundaries. Accessed 28 September 2026; Travel Ruter’s measured receipts, rather than documentation examples, establish the reported cache values.
[5] Pydantic. Instrument Pydantic AI: trace every agent step. Agent, model and tool observability. Accessed 28 September 2026.
[E1] Travel Ruter. Portuguese holdout, 28 September 2026. Frozen scenarios, paired execution, response grades, provider receipts, request transitions and development Logfire reconciliation. Project artifacts are retained by the author and are not publicly archived or independently reviewed.
[E2] Travel Ruter exploratory integration and note-format studies, 19–20 September 2026. Retained by the author to document the three candidate applications and the decision to drop web filtering; their results are not pooled with this study.